Executive Overview
Vocal samples are the lifeblood of contemporary electronic music production, hip-hop, and pop. Whether it is an emotive acapella, a crisp pop stem, or a gritty slice of vintage film dialogue, a well-timed human voice adds profound depth, narrative weight, and immediate human connection to any production. Yet, producers have long wrestled with a persistent bottleneck: source audio quality. Ripping vocal samples from low-resolution internet videos, muddy bootleg vinyl records, or compressed streaming sources invariably introduces a cocktail of unwanted sonic artifacts—hiss, hum, distortion, room reverberation, and background noise.

For decades, rescuing these raw audio gems required tedious, surgical EQing, phase cancellation tricks, and aggressive multi-band transient shaping, often at the heavy cost of the vocal’s natural warmth and clarity. Enter the modern era of machine learning-powered audio engineering. LALAL.AI—a brand already globally recognized for its industry-standard stem separation software—has fundamentally shifted the paradigm with its latest innovation: Lynx.
Spent following a rigorous year of training neural networks to recognize and dissect "sonic dirt" from the nuanced timber of the human voice, the Lynx algorithm represents a generational leap forward. Designed to operate across web browsers, dedicated desktop applications, mobile platforms, and even direct DAW integration for enterprise tiers, Lynx promises to rescue even the most mangled vocal rips and transform them into mix-ready assets. In this comprehensive review, we put LALAL.AI’s Lynx through a series of grueling real-world tests across movie dialogue, degraded vinyl acapellas, and live rock performance stems, assessing how these cleaned vocals integrate seamlessly into modern club tracks.

Detailed Chronology: The Evolution of Vocal Extraction and the Birth of Lynx
To truly understand the disruptive nature of LALAL.AI Lynx, one must contextualize the historical evolution of how electronic music producers and remixers acquire and manipulate vocals.
The Analog and Bootleg Era
Long before neural networks could separate audio streams with surgical precision, producers relied on physical hardware and luck. In the 1980s, 90s, and early 2000s, dance music producers relied heavily on official 12-inch vinyl singles that featured dedicated "acapella" mixes. When official acapellas were unavailable—which was frequently the case for underground house, techno, and hip-hop producers—underground networks of "bootleg" vinyl compilations flooded specialty DJ record stores.

These bootlegs were notoriously low quality. They were frequently generated by recording a vocal track directly from one turntable to another, compounding surface noise, tracking distortion, and high-frequency roll-off. Producers would spend hours in their project studios utilizing primitive hardware noise gates and early digital restoration tools (such as early iterations of CEDAR or hardware expanders) trying to push down vinyl crackle without eating away at the breathy transients of the vocal performance.
The Rise of Stem Separation AI
The landscape changed drastically in the late 2010s and early 2020s with the advent of deep learning architectures tailored for source separation. Companies like LALAL.AI pioneered neural networks trained on multi-track master recordings. By feeding thousands of hours of isolated vocals and instrumentals into convolutional neural networks (CNNs), these systems learned to predict and reconstruct the spectral components of a human voice trapped inside a mixed master file.

While these early AI models excelled at separating vocals from full instrumentation to create acapellas, they often left behind distinct algorithmic artifacts—commonly known as "musical noise" or watery phase anomalies. Furthermore, if the source material itself was inherently noisy (such as an old field recording, a low-bitrate YouTube rip, or a live bootleg), standard stem separation algorithms would isolate the voice along with the background noise, leaving the producer with a clean vocal that was still coated in persistent hums, clicks, and room reflections.
The Introduction of Lynx
Recognizing this critical limitation, the development team behind LALAL.AI spent over twelve months architecting an entirely new neural network dedicated solely to voice isolation and sonic cleanup: the Lynx algorithm (officially designated as v7 Lynx). Rather than simply separating vocals from instruments, Lynx was specifically trained to audit the spectral fingerprint of the human voice, differentiating between true vocal harmonics and environmental interference. Released as part of LALAL.AI’s comprehensive suite of tools, Lynx bridges the gap between raw, unusable audio rips and pristine, production-ready vocal stems.

Supporting Context & Metrics: Putting Lynx Through Its Paces
To evaluate the true capabilities of the Lynx algorithm, we subjected it to three distinct, notoriously difficult audio scenarios: vintage movie dialogue, a deliberately degraded vinyl-simulation acapella, and a live concert recording featuring overwhelming audience noise.
Workflow and Interface Mechanics
Operating Lynx is designed to be frictionless. Users can drop audio files directly into the web application, the desktop software, or iOS applications. Upon dropping a file, users are presented with two primary processing paths:

- Vocal & Instrumental: Designed for traditional stem separation (extracting a vocal from a completed song).
- Voice & Noise: The home of the Lynx algorithm, engineered specifically for cleaning up spoken word, dialogue, and isolated vocals contaminated by external interference.
Within the Voice & Noise menu, users select the v7 Lynx neural network and choose a noise-canceling intensity level: Mild, Normal, or Aggressive. Additionally, a dedicated de-echo toggle allows the algorithm to tackle room reverberation and slapback delay natively found in poorly treated recording environments. Crucially, LALAL.AI offers a "Create preview" feature, allowing engineers to process a 10-minute preview for free to verify results before committing paid credits to a full render.
Test Scenario 1: Movie Dialogue Cleanup
Cinematic dialogue samples provide immense dramatic weight in genres like speed garage, techno, and industrial. However, sourcing dialogue from public domain films of the early-to-mid 20th century on YouTube frequently yields scratchy, low-fidelity audio saturated with optical sound-track hiss and magnetic tape degradation.

- The Source: A dramatic spoken-word excerpt sourced from a public-domain 1930s horror film, plagued by heavy high-frequency hiss and transient distortion.
- The Treatment: Processed through LALAL.AI using the Normal noise-canceling setting under the Lynx algorithm.
- The Result: The algorithm successfully stripped away the underlying magnetic hum and surface hiss without introducing the "swishing" artifacts common in older spectral repair tools. The core formant frequencies of the speaker’s voice remained intact. After light time-stretching, pitch correction, and transient shaping inside Ableton Live, the dialogue was dropped into a high-energy speed garage arrangement, sitting comfortably alongside heavy sub-bass and crisp breakbeats without masking the mix elements.
Test Scenario 2: Degraded Vinyl Acapella
To simulate the classic underground remix workflow of the 1990s, we engineered a torture test. We took an official vocal stem of Chuck Roberts’ legendary house music anthem "My House" (Fingers Inc.), downloaded it at a low 240p resolution from YouTube, and then deliberately processed it inside Ableton Live using iZotope’s Vinyl plugin to inject heavy analog surface scratches, low-frequency electrical hum, and chaotic vinyl pops.
- The Treatment: The heavily degraded file was fed into LALAL.AI. Given the extreme density of the added artifacts, we initially tested the Aggressive setting. While highly effective at noise removal, it proved slightly heavy-handed, occasionally attenuating the breathy high-end transients of Roberts’ iconic spoken intro. Dropping the setting back to Normal—while enabling the de-echo parameter to tame the track’s original slapback delay—yielded a remarkably balanced result.
- The Output: LALAL.AI provides both the cleaned vocal file and a separate file containing only the extracted noise. Listening to the extracted noise file revealed an astonishing level of precision: the algorithm managed to isolate the deliberate vinyl crackle and digital compression artifacts while leaving the rich, baritone weight of the vocal completely untouched. Integrated into a UK garage (UKG) production supplemented by saturators, compression, and modern spatial effects, the rescued acapella sounded punchy, clear, and modern.
Test Scenario 3: Live Concert Stem Extraction and De-Noising
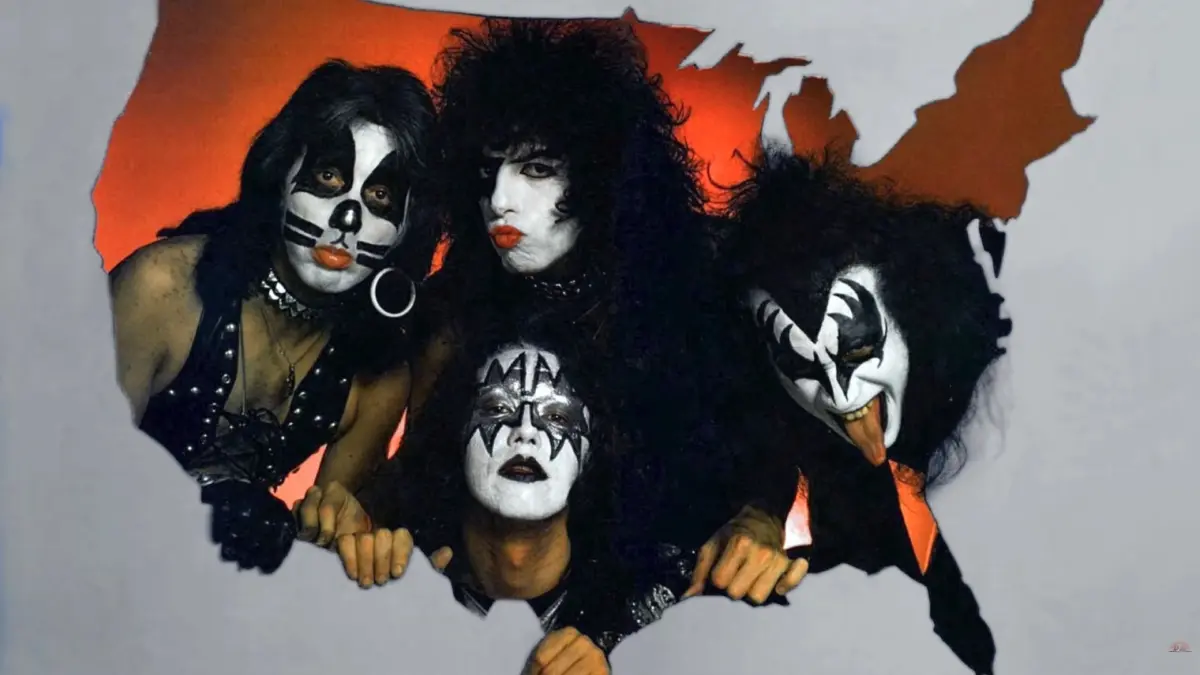
For our final test, we pushed the software to its absolute limit by targeting a live recording: a snippet of the rock band Kiss performing "Do You Love Me?" from their live album archive Kiss Destroys Anaheim 76. Live recordings present a nightmare for producers due to deafening audience cheers, handclaps, stage bleed, and ambient arena acoustics.

- The Workflow: First, the raw live snippet was processed using the Vocal & Instrumental algorithm to extract the lead vocal from the live instrumentation. Naturally, the initial vocal stem still contained prominent crowd cheering and ambient stage wash. We then took that extracted stem and ran it through a second pass using the Voice & Noise Lynx engine on Normal mode with de-echo engaged.
- The Result: The dual-pass workflow successfully excised the intrusive crowd noise and reverberant wash, leaving an astonishingly dry, intelligible lead vocal. When dropped into an aggressive acid house framework—bolstered by TB-303 style squelches, heavy tape saturation, and parallel compression—the vintage live rock vocal was transformed into a commanding, underground club focal point.
Official Statements & Industry Reception
The release of the Lynx algorithm has generated considerable discourse within professional audio engineering and electronic music production circles. Industry veterans and bedroom producers alike have praised LALAL.AI for democratizing audio restoration tools that were once exclusive to high-end post-production facilities utilizing expensive proprietary suites like iZotope RX or Cedar Studio.
In a recent technical breakdown published on their official development blog, the engineering team behind LALAL.AI emphasized the mathematical and architectural hurdles overcome during the year-long training phase of Lynx:

"Training a neural network to clean vocals is fundamentally different from teaching it to remove music," noted the lead audio researcher at LALAL.AI. "Music has predictable harmonic structures, tempo grids, and frequency distributions. The human voice, however, is infinitely variable—it encompasses whispers, screams, gravel, vibrato, and dynamic shifts. The challenge with Lynx was teaching the network to recognize the microscopic boundary between vocal character and environmental noise, ensuring that warmth and air are never sacrificed in the pursuit of absolute silence."
Early adopters among independent producers and remix engineers have similarly lauded the software’s flexibility, particularly praising its multi-platform availability. The inclusion of a desktop application alongside browser-based processing and professional DAW plugin tiers ensures that Lynx fits seamlessly into disparate studio workflows, whether an engineer is working natively inside Pro Tools, Ableton Live, Logic Pro, or editing audio on an iPad on the go.

Future Outlook: The Next Frontier in Intelligent Audio Restoration
As machine learning models continue to scale in computational efficiency and training dataset diversity, the boundary between professional studio recording environments and lo-fi field acquisition is dissolving entirely. Tools like LALAL.AI Lynx signal a permanent shift in how creators approach sampling and sound design.
In the near future, we can anticipate neural audio models moving beyond reactive noise cancellation toward predictive restoration—intelligently reconstructing missing phonetic information in severely damaged archival recordings or automatically matching the acoustic space of an imported sample to a host project’s master bus in real time.

For electronic music producers, hip-hop beatmakers, and multimedia sound designers, the message is clear: the crate-digging ethos of the digital age no longer requires creative compromise. With algorithms like Lynx handling the heavy lifting of audio forensics, producers are empowered to dig deeper into obscure historical archives, forgotten cinematic gems, and degraded vinyl bootlegs, turning sonic imperfections into raw material for tomorrow’s club anthems.
Pricing and Availability
LALAL.AI Lynx is available immediately across multiple subscription tiers tailored to varying production demands:

- Starter Tier: Free (limited preview and processing minutes).
- Lite Tier: $7.50 per month (expanded processing limits and faster rendering queues).
- Pro Tier: $15.00 per month (full feature access, priority rendering, and DAW plugin integration).
- One-Time Top-Ups: Flexible credit-based packages for occasional users.
For more information or to test the Lynx algorithm on your own vocal stems, visit the official LALAL.AI Voice Cleaner Portal.